How It Works#
This section provides a high-level view of how the application processes audio and video input through two parallel pipelines integrated with a modular backend architecture.

Inputs#
You can upload audio recordings and video files, or provide RTSP video streams through the Web-based UI layer, which supports:
Audio and video upload
Viewing transcription, summaries, mind maps, and classroom statistics
Monitoring video analytics streams with real-time overlays
Localization options (English/Chinese)
The uploaded media is passed to the Backend API, which acts as the gateway to the backend service layer and provides similar capabilities.
Audio Pipeline#
The audio pipeline handles speech-to-text conversion and content summarization:
Audio Pre-processing Cleans and formats audio data using FFmpeg, chunking input into segments for optimal processing.
ASR Component (Automatic Speech Recognition) Converts audio into text through the Audio Analyzer microservice, which provides transcription and optional speaker diarization. The provider is set by
models.asr.providerinconfig.yaml. On Linux, Audio Analyzer requests its models from the sharedmodel-downloadercontainer on first start and reuses them from themodel-cachevolume afterwards:Provider
Models
Downloaded from
OpenVINO™ (default)
Whisper (e.g.
whisper-base)Hugging Face (
openai/whisper-*) viamodel-downloader, exported to OpenVINO IRFunASR
Paraformer (
paraformer-zh), for MandarinModelScope via
model-downloader. On Windows,model_hub: huggingfacemoves only the VAD and CAM++ models to Hugging FaceOpenAI
Whisper (e.g.
whisper-base)OpenAI’s public
openai-whispercheckpoints (fetched directly)Speaker Diarization Identifies and separates individual speakers using Pyannote Audio models. This can be enabled or disabled by modifying
config.yaml.Summarizer Component Generates concise summaries of transcribed text using the OpenVINO™ LLM provider.
Content Segmentation The LLM segments the transcript into 15–25 topic-based sections, each of which is encoded and indexed into the vector store. Users can then search lecture content by natural-language queries, retrieving the most relevant topic segments.
Video Analytics Pipeline#
The Video Analytics (VA) pipeline performs real-time video analysis using Deep Learning Streamer (DL Streamer) and OpenVINO™, processing multiple concurrent video streams to extract classroom engagement data.
Pipeline Architecture#
The VA pipeline runs three independent processing streams simultaneously:
Front Video Pipeline — Student-facing camera stream for detailed person tracking, pose estimation, posture classification, hand-raise recognition, and person re-identification
Back Video Pipeline — Rear-view camera stream for broader classroom monitoring and basic pose analysis
Content Pipeline — Interactive flat panel display (IFPD) or board capture, processed at 1 FPS for content frame analysis
Each pipeline is built as a DL Streamer processing graph with the following stages:
Video Decode and Preprocessing — Input from RTSP stream or video file is decoded and preprocessed with hardware acceleration (D3D11)
Person Detection and Pose Estimation — YOLO models (YOLOv8m-pose for front, YOLOv8s-pose for back) detect persons and estimate 17-keypoint skeletons per frame
Posture Detection — A custom DL Streamer element analyzes keypoint geometry to classify posture (sit/stand) and detect hand-raises
Re-identification and Classification:
Person-ReID-retail-0288 re-identifies standing students across frames (front pipeline)
ResNet-18 classifies whole frames of the content pipeline
On Linux, the front and back pipelines also run per-person ResNet-18 classification, and the front pipeline MobileNet-V2 classification; the Windows application does not run these branches
Output — Annotated video is streamed via RTSP through a MediaMTX media server; per-frame metadata is written as JSON for statistics aggregation
Classroom Statistics#
The VA pipeline aggregates per-frame metadata into classroom engagement statistics:
Student count — Number of students detected by the front pipeline. On Windows, each one-minute window takes the median of its per-frame counts, which smooths out frames where a student is briefly missed or detected twice, and the class value is the median over all windows, so the minutes when students are arriving or leaving do not skew it. The window length and percentile are set by
count_bucket_secandcount_percentileunderva_pipeline.pose_statisticsinconfig.yaml. On Linux, the count is the average over the most recent 150 frames (VA_POSE_STUDENT_COUNT_WINDOW_FRAMES).Stand-up events — Per-student stand-up detection with noise filtering
Hand-raise events — Per-student hand-raise tracking with configurable confirmation thresholds
Per-student tracking — Re-identified students are tracked across frames with unique IDs
Streaming and Distribution#
A Media Server (MediaMTX) receives processed video from all three pipelines and provides:
RTSP streaming for real-time playback
HLS/WebRTC streaming for browser-based viewing
Board Content OCR#
Extracts text from the IFPD or whiteboard captured by the content pipeline, enabling post-class review of all written or projected content.
Frame Extraction — FFmpeg (Intel QSV hardware decode) samples JPEG frames at a configurable rate (default: 1 fps every 3 seconds).
Deduplication — Frames with fewer than 0.1% of pixels changed by more than 25 intensity units are skipped.
OCR and Confidence Gating — PaddleOCR extracts text; frames with mean confidence below threshold are dropped.
Post-processing — Near-duplicate consecutive records are merged to reduce downstream LLM token usage.
Output — Results are written as JSON-lines to
board_ocr.txt({frame, source_frame, timestamp, text}).Summary integration — When Board OCR has captured text for a session, the audio summarization step folds it into the AI-generated class summary as an extra “Board / IFPD Content” section, alongside the sections derived from the transcript. If no board text is available, the summary is unchanged.
Content Search Pipeline#
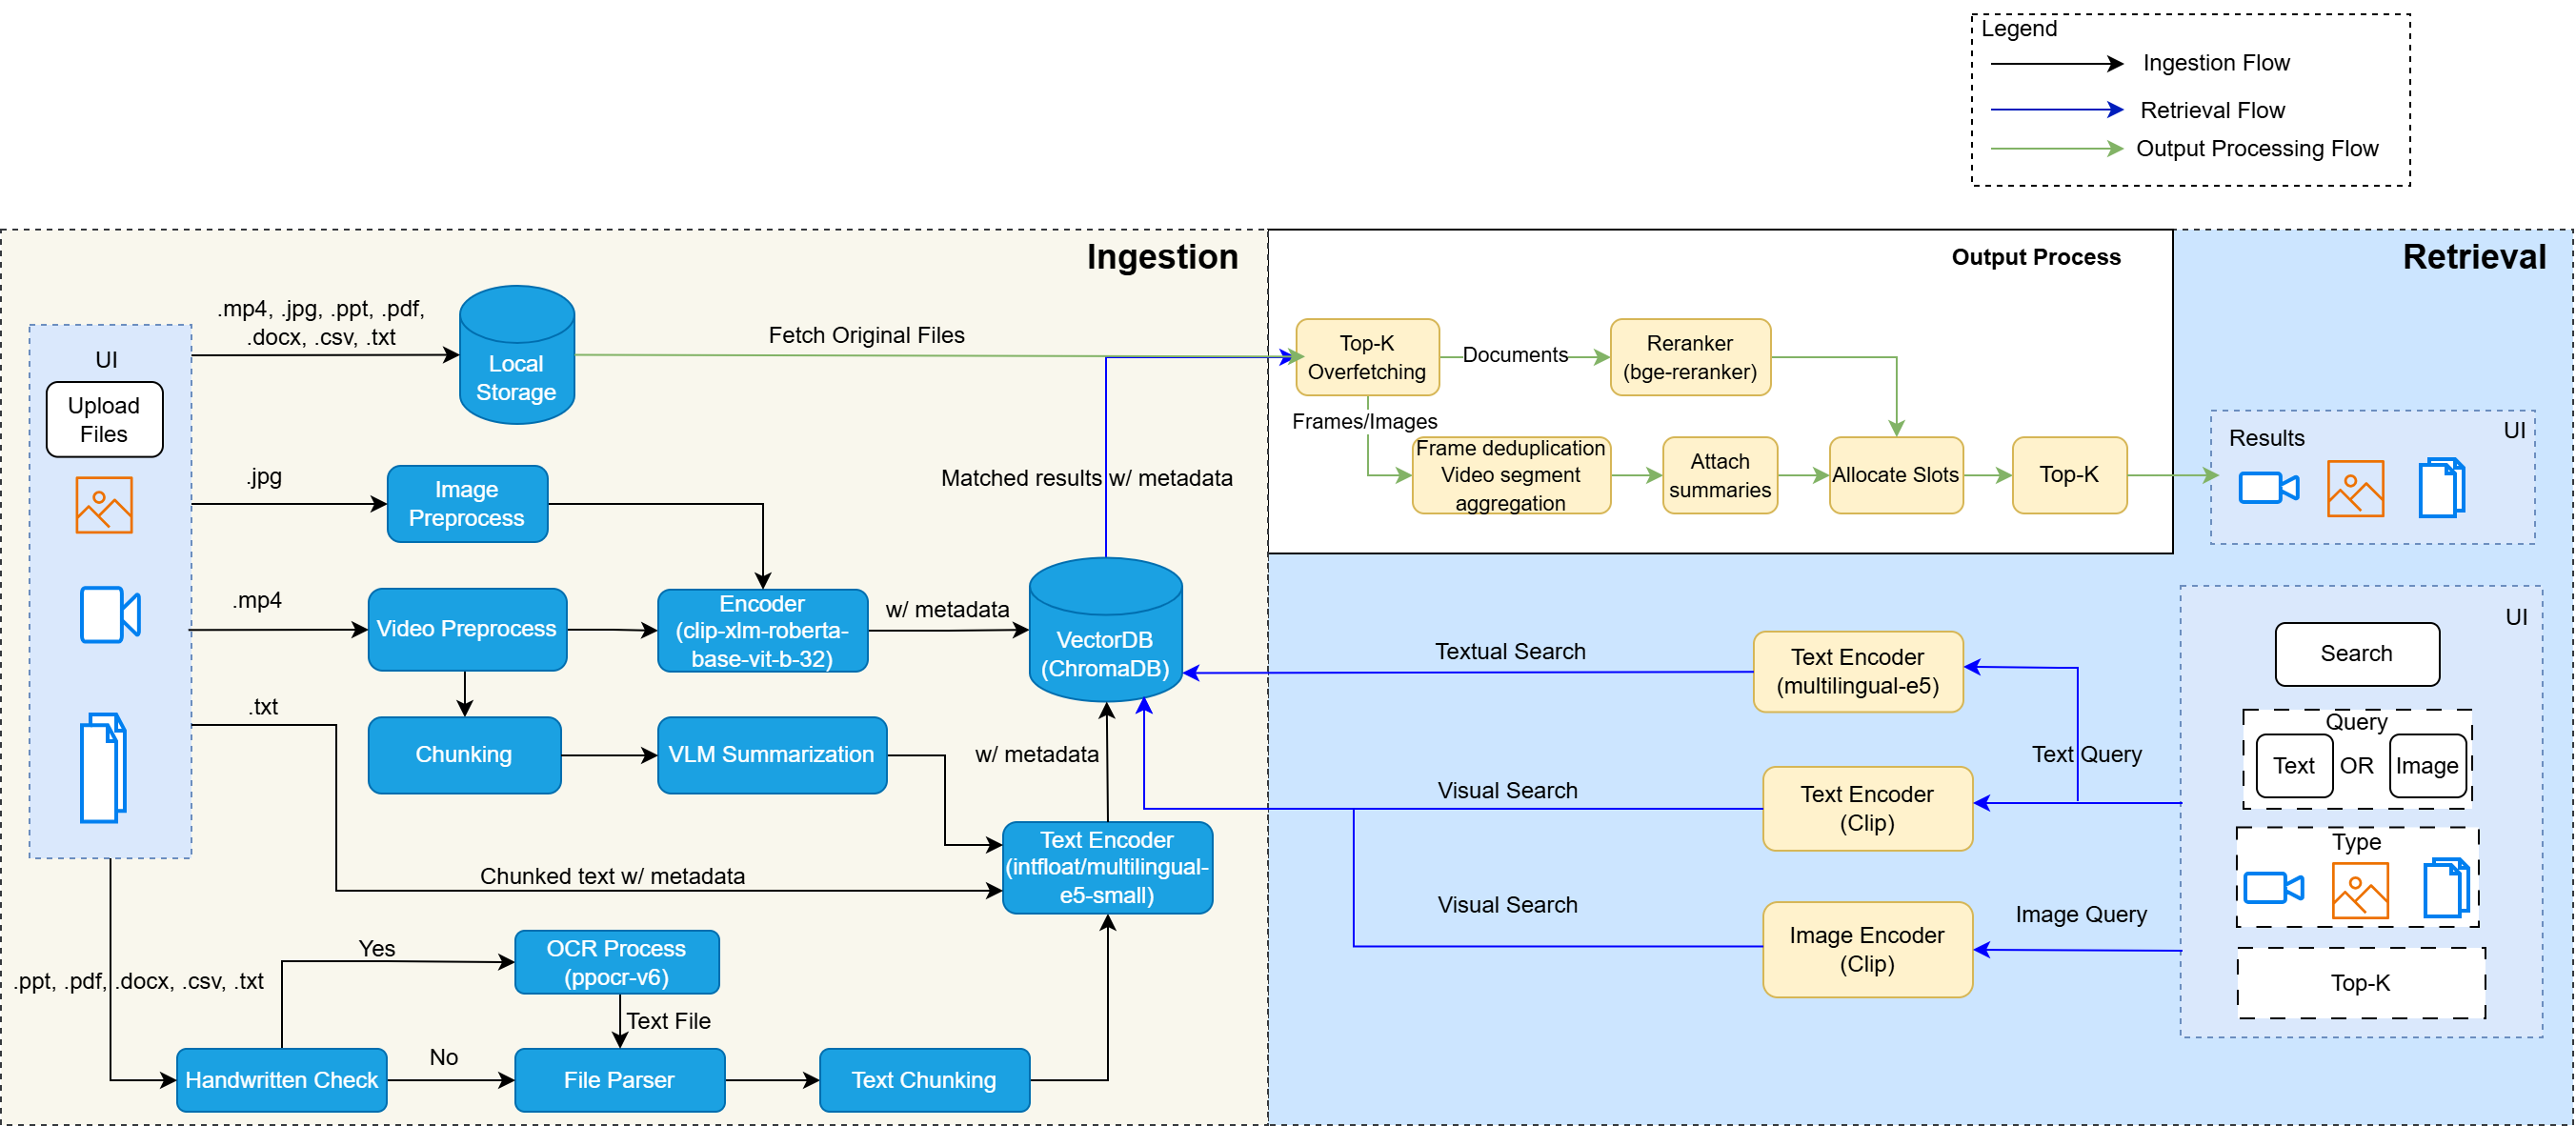
The Content Search pipeline provides multimodal ingestion, semantic indexing, and retrieval across videos, documents, and images.

Ingestion#
Video: Split into time-based chunks (default 30s with 4s overlap), and each chunk’s sampled frames are summarized by a Vision Language Model (Qwen2.5-VL via OpenVINO™). Summaries are indexed as text embeddings; frames are indexed as visual embeddings.
Document: Full-text extraction via
unstructuredwith image OCR via PaddleOCR service. Text is split using semantic chunking (embedding-based boundary detection) or fixed-size chunking, then embedded with BGE (bge-small-en-v1.5).Image: Embedded directly via CLIP (xlm-roberta-base-ViT-B-32) for visual similarity search.
All embeddings are stored in ChromaDB across two collections: a visual collection (CLIP embeddings for images/video frames) and a textual collection (BGE embeddings for document chunks/video summaries).
Retrieval and Search#
Text queries search both visual and textual collections. Textual results are reranked by a cross-encoder (BGE-reranker-large). Results from both modalities are merged using Reciprocal Rank Fusion (RRF) for balanced interleaving.
Image queries search the visual collection by CLIP similarity, with temporal deduplication for video frames.
Metadata filtering supports tags, content type, and custom fields.
Question and Answer (RAG)#
The Q&A endpoint retrieves top-k relevant chunks, assembles them as context within a token budget, and sends them together with the user’s question to the VLM to generate a grounded answer with source references.
Microservices#
Service |
Port |
Role |
|---|---|---|
Content Search API |
9011 |
Orchestrator and public API |
File Ingest & Retrieve |
9990 |
Embedding, indexing, and retrieval |
Video Preprocess |
8001 |
Video chunking and VLM summarization |
Smart Classroom backend |
8000 |
Vision-language model inference (shared with the main app) |
ChromaDB |
9090 |
Vector database |
For API details, see the Content Search Dev Guide.
Metrics Collector#
Monitors and collects:
xPU utilization for hardware performance
LLM metrics for summarization efficiency
Outputs#
Transcriptions, summaries, mind maps, and topic segments can be accessed from the Web-based UI and file system. The path for the file system is /<project-location>/<your-project-name>/. For example,
/storage/chapter-10/Semantic topic search results are returned via the API, with similarity scores and time-range references into the original recording.
Classroom statistics (student count, stand-up events, hand-raise events) are generated from the video analytics pipeline and displayed in the UI.
Video streams with real-time detection overlays are available via RTSP and HLS/WebRTC.
Performance metrics (e.g., utilization, model efficiency) are displayed for monitoring.
Localization ensures outputs are available in multiple languages (English/Chinese).
Learn More#
System Requirements: Hardware, software, supported models, and weight formats.
Get Started: Installation and setup instructions.
Application Flow: End-to-end application flow.
Content Search Flow: The flow of the content search functionality.